Key highlights:
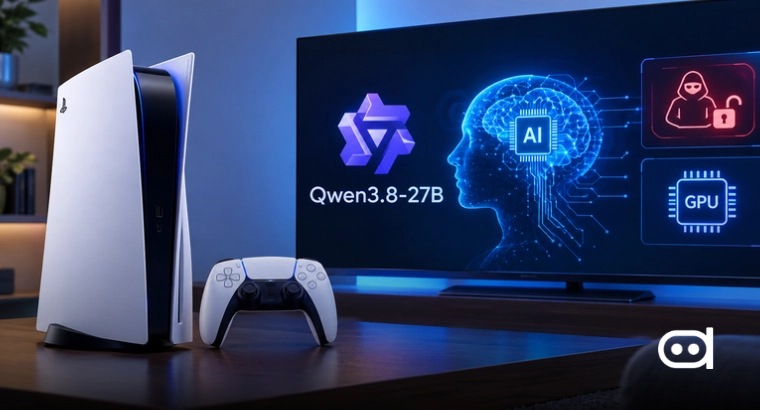
- The PS5LM project reportedly ran Qwen3.8-27B on a jailbroken PlayStation 5, using its GPU.
- An optimized setup increased available memory from 6GB to 11.4GB.
- The heavily compressed model reached 20.9 tokens per second.
- Smaller models went faster, with Llama 3.2 3B hitting 124 tokens per second.
The PlayStation 5 is built for gaming, but a recent experiment looked at what it can do with AI. This project, called PS5LM, ran a large language model, Qwen3.8-27B, on the console using a special software hack that leverages the PS5’s graphics chip. The experiment shows that consumer devices can sometimes handle tasks they weren’t exactly designed for. Of course, fitting a huge AI model into the PS5’s limited memory meant some compromises.
The results show how much software tweaking matters when you’re running AI on hardware not made for it. The console could give responses pretty quickly, but only after it was jailbroken, had a custom software port, and ran a super-compressed model. So it’s more of a technical milestone than something regular users can use to turn their consoles into AI machines right now.
PS5LM Uses a Different Approach to Running AI Models
The experiment builds off earlier work with an unofficial version of llama.cpp, a tool for running large language models locally. Reddit user u/metover figured out how to run AI models on a PS5 by using the CPU as a payload. But this first try was pretty limited: only 6GB of memory was available. That made it tough to run bigger models, especially those that need lots of memory for their settings and prompts. The PS5’s 16GB GDDR6 memory pool couldn’t all be used for AI processing.
Another Reddit user took a different tack. This project brought llama.cpp to the PS5 as a native app, using Vulkan through a RADV port. RADV is an open-source AMD graphics driver that’s part of Mesa. This update reportedly pushed the available memory for AI from 6GB to 11.4GB. That much space finally let a bigger language model fit, though it still required heavy compression.
A jailbroken PS5 is now being used to run a powerful AI model directly on the console. A project called PS5LM has managed to run Qwen 3.8 27B, an AI model with around 27 billion parameters, using the PS5’s GPU. The PS5 has only 16GB of memory, so the AI model needs heavy compression to fit, even with that limitation, it can generate around 21 tokens per second. Smaller AI models are much faster. Tests reached around 61 tokens per second with Gemma 4 E4B and up to 124 tokens per second with Llama 3.2 3B. During the test, the PS5’s GPU was working at 100%, while the CPU was barely being used. The console used around 86W of power and reached about 54°C.
— Pirat_Nation 🔴 (@Pirat_Nation) October 14, 2026
Heavy Quantization Makes Qwen3.8-27B Fit
The main model tested was Qwen3.8-27B. With about 27 billion parameters, it needs a ton of memory. At full 16-bit precision, it would take 54GB, way more than the PS5’s 16GB memory. To work around that, the project used Qwen3.8-27B-UD-IQ2_XXS, a version where model weights are stored at roughly 2 bits each. That shrank the size to 6.8GB, which finally fit within the PS5’s limits.
However, this reduction comes with a trade-off. Compressing a model this much reduces memory use, but the output isn’t as good. It makes more mistakes and reasoning weakens. So running a 27-billion-parameter model on PS5 isn’t the same as running it with more memory and higher precision. They also used a 64K context window, and total memory use reportedly reached 91 percent. That leaves little room for anything else, and it shows how tightly the setup runs up against the PS5’s hardware limits.
GPU Performance Delivers Different Speeds Across Models
The PS5’s 448GB/s memory bandwidth played a big role in this experiment. Qwen3.8-27B generated 20.9 tokens per second, with the GPU maxed out (100 percent) while the CPU did little (just 2 percent).
Smaller models ran much faster. Gemma 4 E4B reportedly reached 61 tokens per second. Llama 3.2 3B was even quicker, at 124 tokens per second. So, the model’s size and memory demands really matter for how fast the PS5 can generate text.
The test also measured power and temperature. The console reportedly consumed 86W and hit around 54°C while under load. These numbers show what the system looked like during the test, but they don’t guarantee the same performance on other models or uses.
Jailbreak Requirement Remains a Major Limitation
Even with these impressive results, practical restrictions remain. Running the native llama.app requires a jailbroken PS5, which isn’t typical or recommended for the average user. Jailbreaking also voids your warranty and could get you banned from online games.
Memory is another barrier. The optimized setup can fit a highly compressed 27-billion-parameter model, but anything bigger or more precise is out of reach. You also have to accept the drop in AI quality that comes with squeezing the model down so much.
So, PS5LM shows what’s possible by pushing software and GPU use, but it also makes clear why memory limits and other system restrictions are still huge challenges if you want to turn gaming hardware into a platform for local AI.